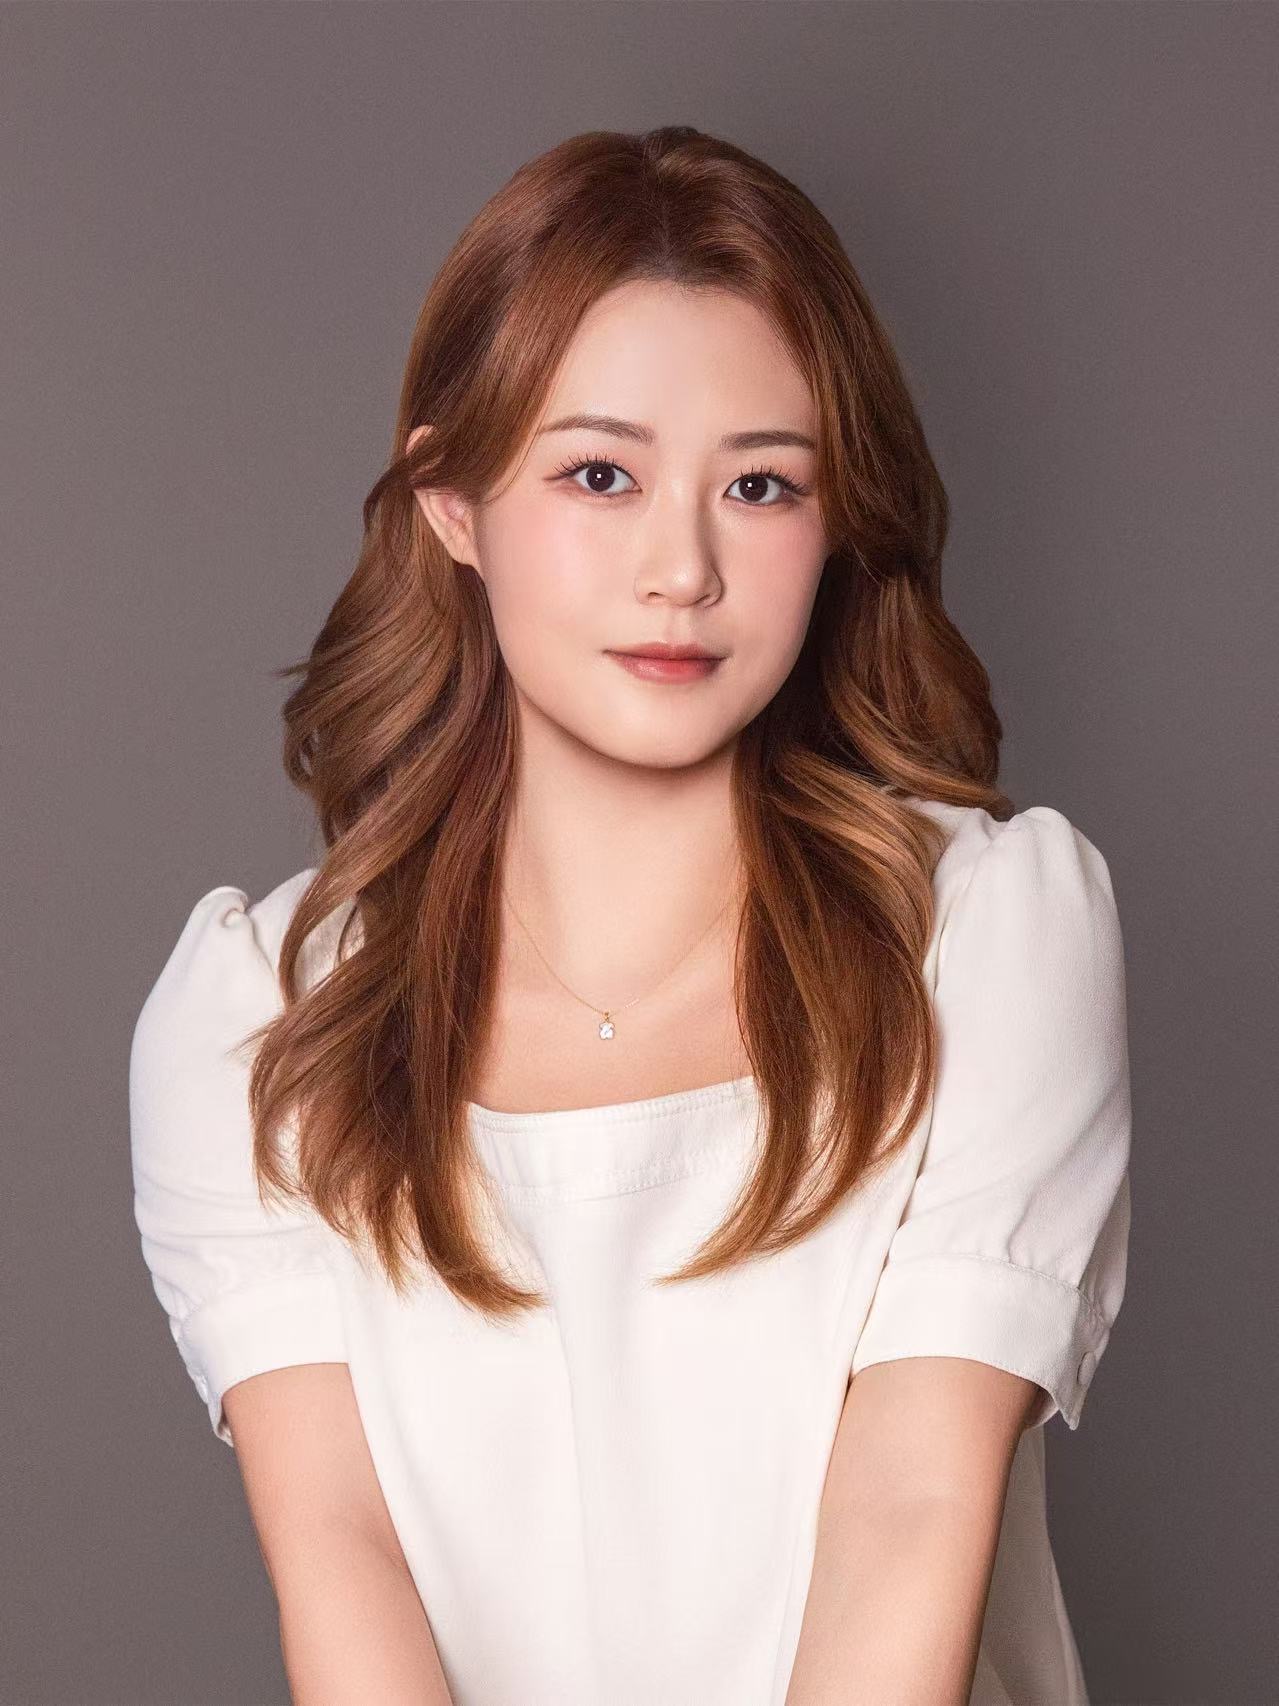
I am a tenure-track Assistant Professor in the School of Artificial Intelligence (SAI) at The Chinese University of Hong Kong, Shenzhen (CUHK-Shenzhen), China. Before joining CUHK-Shenzhen, I was a Research Scientist at A*STAR, Singapore, an Associate Faculty at the Singapore Institute of Technology (SIT), teaching the Large Language Models module, and a Research Fellow in the Department of Electrical and Computer Engineering (ECE) at the National University of Singapore (NUS). I have received a Ph.D. degree from the National University of Singapore, supervised by Prof. Haizhou Li (IEEE Fellow) and Prof. Shuzhi Sam Ge (IEEE Fellow). During my PhD studies, I was a visiting research scholar at National Institute of Informatics (Japan), supervised by Prof. Junichi Yamagishi. I received a B.Sc degree from Nanjing University, Nanjing, China in 2017.
My research interest includes multilingual speech and audio intelligence, multimodal language models, music and singing processing, and trustworthy AI. I have published high-impact top-tier AI journals and conferences, including IEEE Transaction on Audio, Speech and Language Processing (TALSP), IEEE Transactions on Multimedia (TMM), IEEE Signal Processing Letters (SPL), Speech Communications, IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), ACL, EMNLP, AAAI, INTERSPEECH, IEEE ASRU, IEEE APSIPA ASC, IEEE Spoken Language Technology Workshop (SLT), Transactions of the Association for Computational Linguistics (TACL) and Pattern Recognition Letters.
🔥🔥 I am recruiting fully funded PhD students, Research Assistants/Research Engineers, Master’s students, Research interns (on-site or remote) and Visiting students to work on research in speech, singing, multimodal AI, and trustworthy AI. Students and researchers will have access to extensive GPU resources and opportunities to collaborate with leading researchers such as Prof. Haizhou Li (IEEE Fellow). Outstanding candidates may also be recommended for PhD programs and research internships at top universities and research labs in Singapore, the US, Japan, and the UK, as well as opportunities at top-tier technology companies and industrial research labs such as Google DeepMind, Meta, and Microsoft. If you are interested, email me at gaoxiaoxue@cuhk.edu.cn with your CV and indicate the position you are applying for. Please review CUHK-Shenzhen SAI’s admission requirements on the official website before contacting me.🔥🔥
🔥🔥 Master of Philosophy and PhD Application Deadlines:🔥🔥
📅🌱Spring 2027 Intake: 31 October 2026,apply at https://sai.cuhk.edu.cn/en/node/35
📅🍂Fall 2027 Intake: 31 May 2027, apply at https://sai.cuhk.edu.cn/en/node/35
⭐ Applications are reviewed on a rolling basis. Early applications are strongly encouraged!
🔥 News
- 2026: 🎉🎉 Dr. Gao serves as one of the organizers of AACL 2026 TrustAudio workshop! More details for paper submissions in the TrustAudio website!
- 2026: 🎉🎉 One Signal Processing Letters paper has been accepted for publication!
- 2026: 🎉🎉 Two APSIPA papers have been accepted for publication!
- 2026: 🎉🎉 Two Interspeech papers have been accepted for publication!
- 2026: 🎉🎉 Our IJCAI paper has been accepted for publication!
- 2026: 🎉🎉 Dr. Gao serves as one of the organizers of VoiceMOS Challenge 2026! Join us through the VoiceMOS 2026 website.
- 2026: 🎉🎉 Our ACL paper has been accepted for publication!
- 2026: 🎉🎉 Our Pattern Recognition Letters has been accepted for publication!
- 2026: 🎉🎉 Our TACL paper has been accepted for publication!
- 2025: 🎉🎉 Dr. Gao serves as one of the organizers of AAAI 2026 worshop on audio AI. Our AAAI 2026 workshop has been accepted and is now open for submissions! 🌟 Check it in audio-aaai.
- 2025: 🎉🎉 Dr. Gao serves as one of the advisory board of ICASSP 2026 grand challenge. Our ICASSP 2026 grand challenge has been accepted and is now open for submissions! 🌟 Check it in ICASSP 2026 Cadenza Challenge website.
- 2025: 🎉🎉 Our IEEE ASRU paper has been accepted for publication!
- 2025: 🎉🎉 Our ACL paper has been accepted for publication!
- 2025: 🎉🎉 Our TALSP regular paper has been accepted for publication!
- 2024: 🎉🎉 Our ICASSP paper has been accepted for publication!
- 2024: 🎉🎉 Our AAAI has been accepted for publication!
- 2024: 🎉🎉 Our TMM has been accepted for publication!
- 2024: 🎉🎉 Our EMNLP has been accepted for publication!
- 2024: 🎉🎉 Two Signal Processing Letters have been accepted for publication!
- 2023: 🎉🎉 Dr. Gao was invited as the leading Guest Editor of the special issue “Modeling of Multimodal Speech Recognition and Language Processing” in Electronics (IF:2.9, ISSN 2079-9292).
- 2023: 🎉🎉 Our TALSP regular paper has been accepted for publication!
- 2023: 🎉🎉 Two papers have been accepted by ICASSP 2023!
- 2020: 🎉🎉 Won first places for two tasks in Automatic Lyrics-to-Audio Alignment Task in Music Information Retreval Evaluation eXchange International Benchmarking Competition 2020. Check it in NUS ECE news.
- 2019: 🎉🎉 Received Best Poster Award Runner Up Prize at 4th Workshop for Young Female Researchers in INTERSPEECH, Graz, Austria. Check it in NUS ECE news.
📜 Research Area
| Speech and Audio Intelligence : Automatic speech recognition;Speech Emotion Recognition; Speech synthesis; Audio captioning; Agentic AI in speech and audio. |
Singing and Music Processing : Speech-to-singing conversion; Singing voice conversion; Singing generation; Lyrics-to-audio alignment; Chord transcription; Music source separation; Musical genre recognition. |
Trustworthy AI : Audio security and safety; Robustness and adversarial security; Fairness and bias in speech AI; LLM Jailbreak and safety alignment. |
| Multi-modal Processing: Audio-visual active speaker detection; Large audio language models; Multimodal generation. |
Self-supervised Learning : Self-supervised speech processing; Self-supervised language processing. |
Large Language Models : Large audio language models; Speech LLMs; Speech synthesis with large language models; Multilingual LLMs. |
💻 Research Experiences
- 2026.08 - Present, Assistant Professor, The Chinese University of Hong Kong, Shenzhen (CUHK-Shenzhen), China.
- 2024.02 - 2026.08, Research Scientist, A*STAR, Singapore.
- 2023.11 - 2024.01, Visiting Researcher, Academia Sinica.
- 2022.11 - 2023.11, Research Fellow, National University of Singapore (NUS), Singapore.
- 2022.07 - 2022.08, Research Scholar, National Institute of Informatics, Japan.
📖 Educations
- 2017.08 - 2022.10, Ph.D. in Electrical and Computer Engineering, National University of Singapore (NUS), Singapore.
- 2013.09 - 2017.07, B.Sc. in Electronic Information Science and Technology, Nanjing University, Nanjing, China.
📝 Publications
– Journal Papers –
- Jianan Chen, Xiaoxue Gao
*, Kawahara Tatsuya and Nancy F. Chen, LoASR-Bench: Evaluating Large Speech Language Models on Low-Resource Automatic Speech Recognition Across Language Families, SPL, 2026. - Yiming Chen, Xianghu Yue, Chen Zhang, Xiaoxue Gao
*, Robby T. Tan and Haizhou Li, Voicebench: Benchmarking llm-based voice assistants, Transactions of the Association for Computational Linguistics (TACL), 2026. - Xianghu Yue, Xueyi Zhang, Xiaoxue Gao, Mengling Feng, Mingrui Lao, Huiping Zhuang, Haizhou Li, Pal: Prompting analytic learning with missing modality for multi-modal class-incremental learning, Pattern Recognition Letters, 2026.
- Xiaoxue Gao, Huayun Zhang and Nancy F. Chen, Prompt-Unseen-Emotion: Mixed Emotional Speech Synthesis With Prompt-LLM Contextual Knowledge, SPL, 2025.
- Xiaoxue Gao, Yiming Chen, Xianghu Yue, Yu Tsao and Nancy F. Chen, TTSlow: Slow Down Text-to-Speech with Efficiency Robustness Evaluations, TALSP, 2025.
- Ruijie Tao, Xinyuan Qian, Rohan Kumar Das, Xiaoxue Gao, Jiadong Wang and Haizhou Li, Enhancing Real-World Active Speaker Detection with Multi-Modal Extraction Pre-Training, TMM, 2024.
- Xiaoxue Gao, Zexin Li, Yiming Chen, Cong Liu and Haizhou Li, Transferable Adversarial Attacks against ASR, SPL, 2024.
- Duo Ma, Xianghu Yue, Junyi Ao, Xiaoxue Gao, Jiadong Wang and Haizhou Li, Text-guided HuBERT: Self-Supervised Speech Pre-training via Generative Adversarial Networks, SPL, 2024.
- Xianghu Yue, Xiaoxue Gao
*, Xinyuan Qian, Haizhou Li, Adapting Pre-Trained Self-Supervised Learning Model for Speech Recognition with Light-Weight Adapters, Electronics, 2024. - Xiaoxue Gao, Chitralekha Gupta, Haizhou Li, PoLyScriber: Integrated Fine-tuning of Extractor and Lyrics Transcriber for Polyphonic Music, TALSP, 2023.
- Xiaoxue Gao, Chitralekha Gupta, Haizhou Li, Automatic Lyrics Transcription of Polyphonic Music with Lyrics-Chords Multi-Task Learning, TALSP, 2022.
- Bidisha Sharma, Xiaoxue Gao, Karthika Vijayan, Xiaohai Tian and Haizhou Li, NHSS: A Speech and Singing Parallel Database, Speech Communication, 2021.
– Conference Papers –
- Zi Haur Pang, Xiaoxue Gao
*, Kawahara Tatsuya and Nancy F Chen, ERM-MinMaxGAP: Benchmarking and Mitigating Gender Bias in Multilingual Multimodal Speech-LLM Emotion Recognition, Interspeech, 2026. Non-archival@ICML Workshop - Yihang Lin, Li Zhou, Congwei Cao, Dongchu Xie, Xiaoxue Gao, Chen Zhang and Haizhou Li, Emo-LiPO: Listwise Preference Optimization for Fine-Grained Emotion Intensity Control in LLM-based Text-to-Speech, IJCAI, 2026.
- Weihua Zheng, Zhengyuan Liu, Tanmoy Chakraborty, Weiwen Xu, Xiaoxue Gao, Bryan Chen Zhengyu Tan, Bowei Zou, Chang Liu, Yujia Hu, Xing Xie, Xiaoyuan Yi, Jing Yao, Chaojun Wang, Long Li, Rui Liu, Huiyao Liu, Koji Inoue, Ryuichi Sumida, Tatsuya Kawahara, Fan Xu, Lingyu Ye, Wei Tian, Dongjun Kim, Jimin Jung, Jaehyung Seo, Nadya Yuki Wangsajaya, Pham Minh Duc, Ojasva Saxena, Palash Nandi, Xiyan Tao, Wiwik Karlina, Tuan Luong, Keertana Arun Vasan, Roy Ka-Wei Lee, and Nancy F Chen, MMA-ASIA: A Multilingual and Multimodal Alignment Framework for Culturally-Grounded Evaluation, ACL, 2026.
- Xiaodan Chen, Xiaoxue Gao
*, Mathias Quoy, Alexandre Pitti, Nancy F Chen, Confidence-Based Self-Training for EMG-to-Speech: Leveraging Synthetic EMG for Robust Modeling, ASRU, 2025. - Zhengyuan Liu, Geyu Lin, Hui Li Tan, Huayun Zhang, Yanfeng Lu, Xiaoxue Gao, Stella Xin Yin, He Sun, Hock Huan Goh, Lung Hsiang Wong and Nancy F. Chen, SingaKids: A Multilingual Multimodal Dialogic Tutor for Language Learning, ACL, 2025.
- Xiaoxue Gao, Chen Zhang, Yiming Chen, Huayun Zhang and Nancy F. Chen, Emo-dpo: Controllable emotional speech synthesis through direct preference optimization, ICASSP, 2025.
- Kuluhan Binici, Abhinav Ramesh Kashyap, Viktor Schlegel, Andy T Liu, Vijay Prakash Dwivedi, Thanh-Tung Nguyen, Xiaoxue Gao, Nancy F Chen, Stefan Winkler, MEDSAGE: Enhancing Robustness of Medical Dialogue Summarization to ASR Errors with LLM-generated Synthetic Dialogues, AAAI, 2025.
- Yiming Chen, Xianghu Yue, Xiaoxue Gao, Chen Zhang, Luis Fernando D’Haro, Robby T. Tan and Haizhou Li, Beyond Single-Audio: Advancing Multi-Audio Processing in Audio Large Language Models, EMNLP, 2024.
- Xiaoxue Gao and Nancy F. Chen, Speech-Mamba: Long-Context Speech Recognition with Selective State Spaces Models, SLT, 2024.
- Xiaoxue Gao, Xianghu Yue, Haizhou Li, Self-Transriber: Few-shot Lyrics Transcription with Self-training, ICASSP, 2023.
- Xianghu Yue, Xiaoxue Gao
*, Haizhou Li, token2vec: A Joint Self-Supervised Pre-training Framework Using Unpaired Speech and Text, ICASSP, 2023. - Xiaoxue Gao, Chitralekha Gupta, Haizhou Li, Genre-conditioned Acoustic Models for Automatic Lyrics Transcription of Polyphonic Music, ICASSP, 2022.
- Xiaoxue Gao, Chitralekha Gupta, Haizhou Li, Music-robust Automatic Lyrics Transcription of Polyphonic Music, SMC, 2022.
- Xiaoxue Gao, Chitralekha Gupta, Haizhou Li, Lyrics Transcription and Lyrics-to-audio Alignment with Music Informed Acoustic Models, MIREX, 2020.
- Xiaoxue Gao, Xiaohai Tian, Rohan Kumar Das, Yi Zhou and Haizhou Li, Personalized Singing Voice Generation Using WaveRNN, Speaker Odyssey, 2020.
- Xiaoxue Gao, Xiaohai Tian, Rohan Kumar Das, Yi Zhou and Haizhou Li, Speaker-independent Spectral Mapping for Speech-to-Singing Conversion, IEEE APSIPA ASC, 2019.
- Chitralekha Gupta, Karthika Vijayan, Bidisha Sharma, Xiaoxue Gao and Haizhou Li, NUS Speak-to-Sing: A Web Platform for Personalized Speech-to-Singing Conversion, INTERSPEECH, 2019.
- Karthika Vijayan, Xiaoxue Gao and Haizhou Li, Analysis of Speech and Singing Signals for Temporal Alignment,IEEE APSIPA ASC 2018
- Xiaoxue Gao, Berrak Sisman, Rohan Kumar Das and Karthika Vijayan, NUS-HLT Spoken Lyrics and Singing (SLS) Corpus, IEEE ICOT, 2018
🎖 Honors and Awards
- 2020 Ranked first in Automatic Lyrics-to-Audio Alignment Task in Music Information Retreval Evaluation eXchange International Benchmarking Competition 2020. The winning Lyrics-to-Audio Alignment system NUS Auto Lyrix Align is now available online as an interactive web interface: The winning Lyrics-to-Audio Alignment system NUS Auto Lyrix Align is now available online as an interactive web interface: https://autolyrixalign.hltnus.org/
- 2020 Ranked first in Automatic Lyrics Transcription Task in Music Information Retreval Evaluation eXchange International Benchmarking Competition 2020.
- 2019 Best Poster Award Runner Up Prize, “Speech-to-Singing Conversion and Synthesis” at 4th Workshop for Young Female Researchers in INTERSPEECH, Graz, Austria.
- 2019 ISCA Grants,“Average Modeling for Spectral Mapping in Speech-to-Singing Conversion” at 2019 Speech Processing Courses in Crete Conversational Speech Synthesis: from design to evaluation, University of Crete, Heraklion Crete, Greece.
- 2016 Meritorious Winner (Top 8% winner), American Mathematical Contest in Modeling.
- 2015 National Second Prize, National Undergraduate Electronic Design Contest.
💬 Talks
- 2025.06, Generative AI in Speech: from Muscle Signals to Text, SINFRA 2025, France.
- 2022.08, Automatic Lyrics Transcription of Polyphonic Music, National Institute of Informatics, Japan.
💻 Internships
- 2023.11 - 2024.01, Visiting Researcher, Academia Sinica.
- 2022.07 - 2022.08, National Institute of Informatics, Japan.
📚 Research Web Platform
- Speech and Singing Parallel Database: https://hltnus.github.io/NHSSDatabase/
- Lyrics-to-Audio Alignment Interactive Web Interface 🎼: https://autolyrixalign.hltnus.org/
👔 Projects
- Synthetic Data Generation for Scaling Multilingual Models, A*STAR, Singapore
- Expressive and Empathetic Human-AI Interaction by Enhancing Multilingual, Multi-modal Large Language Model, A*STAR, Singapore.
- Heterogeneous Preference Learning for Value-Aligned Large Language Models in Multicultural Societies: A Resource-Efficient Approach, A*STAR, Singapore.
- Intelligent Modelling for Decision-making in Critical Urban Systems, A*STAR, Singapore
- Building National-Level Capability in Large Language Models “National LLM”, A*STAR, Singapore
- SpeechEval Phase II: SHE4EDU (Speech Highlighter and Evaluation for Education), A*STAR, Singapore
- SingaKids Pic2Speak: Multilingual AI Tutor – Uplifting Singapore’s Bilingual Edge, A*STAR, Singapore
- Human-Robot Collaborative AI for Advanced Manufacturing And Engineering, NUS, Singapore.
- Perfect Singing Vocals, NUS, Singapore.